PASSAGE A · PRODUCTPENDING
Nora support follows policy R-17.
Lighter to deploy. Faster to index. Better at finding evidence.
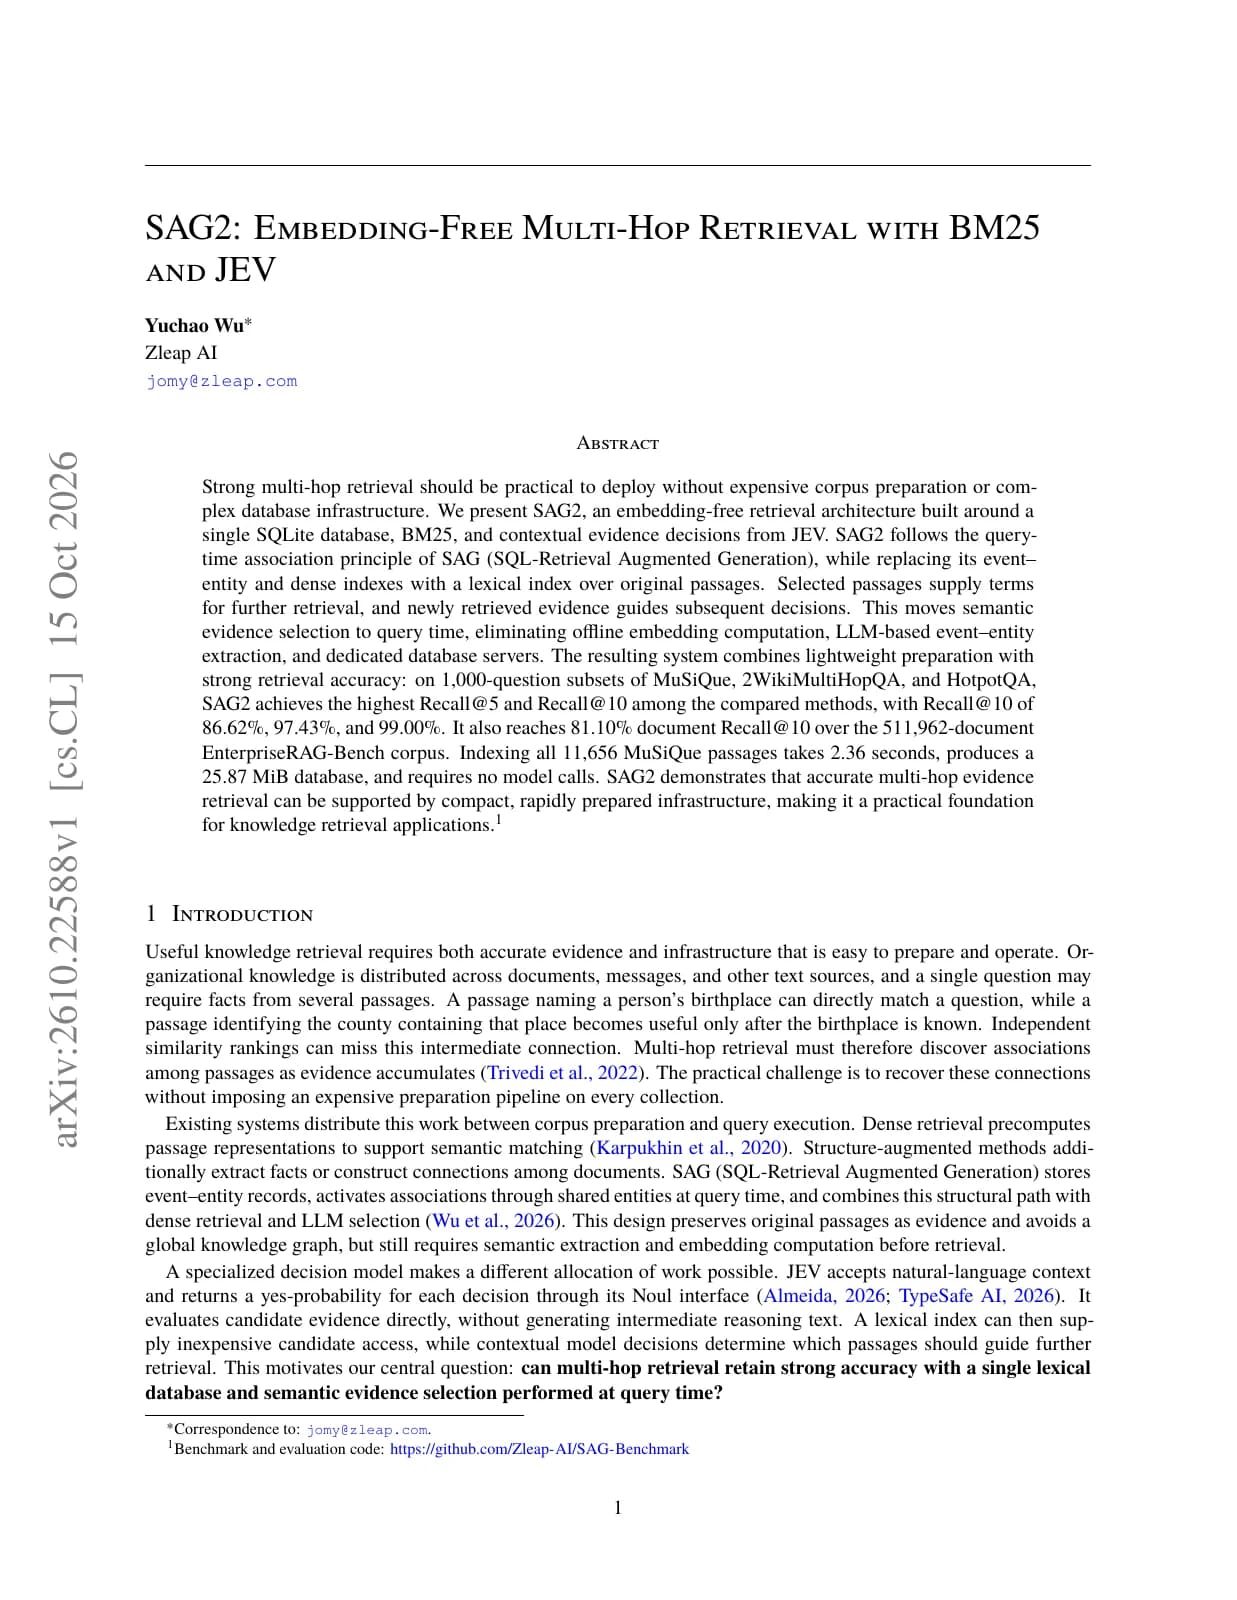
SAG2 builds on SAG's approach to connecting documents. It indexes the original text by keywords, removing LLM processing and embeddings from preparation. When a question arrives, it finds useful passages and follows their terms to retrieve more evidence.
Results from the papers. Benchmarks, metrics and test conditions are explained below.
01 / HOW IT WORKS
SAG2 indexes the original text. At query time, BM25 retrieves passages, JEV selects useful evidence, and terms from that evidence drive another search.
Source text + keyword index → one SQLite file
Local text indexing, with no model callsNora support follows policy R-17.
Nora packaging comes in two colors.
Question + selected passage A → inform the next judgment
Store source passages and term occurrences in SQLite. Build the full-text index locally, with no model calls.
A fictional example illustrating the retrieval process. Select any step to inspect it; autoplay stops after one pass.
VIDEO / SAG2
See how embedding-free indexing, BM25, JEV and successive searches work together.
Video and resources on GitHub02 / BENCHMARKS
Recall@5 measures the required evidence found in the first five results; Recall@10 looks at the first ten. Recovering more of those facts gives an agent a more complete basis for its answer.
+3.25 points vs SAG
1,000 fixed development questions per benchmark; MuSiQue was also used during development. Values follow the SAG2 paper. SAG and SAG2 use different models and implementations, so these compare the complete systems.
| Method | MuSiQue | 2WikiMultiHopQA | HotpotQA |
|---|---|---|---|
| BM25 | 54.41 | 71.50 | 86.90 |
| Contriever | 53.58 | 65.20 | 82.75 |
| BGE-Large-EN-v1.5 | 64.08 | 73.75 | 93.35 |
| GTE-Qwen2-7B | 70.80 | 78.63 | 93.55 |
| GritLM-7B | 75.19 | 79.40 | 97.20 |
| NV-Embed-v2 | 77.27 | 80.75 | 97.70 |
| HippoRAG 2 | 73.76 | 93.40 | 97.15 |
| SAG | 83.37 | 93.57 | 97.70 |
| SAG2 | 86.62 | 97.43 | 99.00 |
03 / ABLATION STUDY
Use the same 1,000 MuSiQue questions to test fewer search rounds and judgments made without the passages already found.
MuSiQue · Recall@10
Initial retrieval reaches 67.93% Recall@10. One additional search round raises it to 83.36%, and two reach 86.62%.
Judging new passages without the facts already found lowers Recall@10 from 86.62% to 76.25%.
04 / SCALE & PREPARATION
Preparation builds a keyword index directly from the text, without LLMs or embedding models. Below are the indexing measurements and retrieval results on more than half a million documents.
01 / INDEXING COST
2.36s
To index 11,656 source passages by keyword
Timing comes from the paper's experiment; it varies with hardware and the documents being indexed.
02 / RETRIEVAL AT SCALE
81.10%
Required documents found in the top ten · Recall@10
511,962 synthetic documents model company emails, messages, meetings and other records. 470 questions identify the documents needed. Baselines come from the dataset paper with different compute budgets; this measures document retrieval, not generated answers.
05 / DEPLOYMENT
Keep source text and keyword indexes in one SQLite file. Indexing needs no LLM or embedding model calls.
JEV judges passages during semantic retrieval; useful passages drive further searches. Connect your own model to generate answers.
The paper uses fixed test sets. Measure retrieval quality and online speed on your own documents and hardware.
06 / RELATED PRODUCT
A local knowledge base powered by SAG2. Choose a folder to search supported documents, notes and code, then ask questions and check the cited source passages.
Add supported documents, notes and code
Retrieve the relevant passages with SAG2
Return from the answer to the original passages