Zleap-Agent: An Agent Harness with Sparse Attention
How Zleap-Agent isolates context, tools and memory by workspace, using prefetching, on-demand access and database-backed memory to reduce the information each step must process.
Open source: https://github.com/Zleap-AI/Zleap-Agent
Hi, I am Jomy. Since last year, my team and I have been researching local AI deployment inside enterprises.
Enterprise systems have constraints that personal experiments do not. Data cannot freely leave the internal network, and costs cannot grow without limit. We cannot simply assume the largest, most expensive model is available.
We chose small models and have studied how to use local models effectively. SAG, discussed yesterday, handles underlying data retrieval and context generation.
After examining the data layer, we found a similar problem in agent harnesses.
Context windows have grown. GPUs are cheaper, inference frameworks are more mature and models accept more tokens. This encourages the assumption that tools, memories, history and rules should all be added to context.
But a larger window does not make attention cheaper.
Model research addresses this through sparse attention, sliding windows and long-context compression. The shared aim is to avoid making a model examine everything at every step.
We believe the agent harness should do the same, with a simpler approach.
Attention Is Valuable
A longer context window means a model can hold more tokens. It does not mean it can use them accurately at every step.
This is especially true for small local models, whose instruction following and ability to locate information in long context are limited. Adding dozens of tools, hundreds of past interactions and assorted memories and rules first forces the model to filter information.
Many harnesses assume a powerful underlying model. Claude Code, for example, wraps Claude in an agentic coding toolchain for reading code, editing files, running commands, connecting MCP, using hooks and starting sub-agents.
Tools such as OpenClaw and Hermes also add execution environments, tools, long-term memory and automation to models.
These systems matter and advance what agents can do. But as tools, memories, rules and logs grow, the model still has to find its own way through them.
Large models tolerate this better than small ones, making the problem less visible. Wasted attention nevertheless produces slower responses, higher costs and more mistakes.
Workspace
Zleap-Agent begins with a different question: which workspace should the agent be in right now?
Workspace is its most important concept. It is a layer for isolating context and tools, rather than a sub-agent or a tool category alone.
Think of an operating system. The main workspace is the desktop. It should not contain every application's buttons, documents and history. It tells you which applications are available and which one to open.
A sales workspace is like a CRM, with customers, contracts, follow-up records and sales tools. A finance workspace contains invoices, reimbursements, budgets and approval rules. A content workspace contains topics, source material, publishing history and writing experience.
The same agent works at different workstations without seeing everything at once.
A sub-agent, by comparison, is a temporary helper with its own role, prompts and context that returns a result.
In a workspace, the same agent continues working. Its visible tools, context and memory change. Each workspace has its own working memory, which persists there without spilling into the main workspace or other workspaces.
The main workspace coordinates rather than collecting every detail. Giving it all workspaces' memories and tools would recreate the overloaded context we are trying to avoid.
This also means the LLM need not be fixed for the entire agent. Different workspaces can use different models: an inexpensive model for routine conversation, a stronger one for complex analysis, a multimodal model for visual tasks and a local model for sensitive data.
Model routing and local–cloud coordination follow naturally. Local work stays local; work requiring greater capability goes to the cloud. The workspace determines the appropriate model for the task.
Treat Context as Memory
Context should not be treated as a single prompt string.
Concatenating system instructions, persona, tool descriptions, history and memory into one block is too crude.
Zleap-Agent divides context into regions:
Context = System Prompt + Workspace Prompt + Tools + Memory + History
The System Prompt defines the agent's fundamental behavior and persona. It remains consistent across workspaces.
The Workspace Prompt describes the current workspace, its capabilities and its boundaries.
Tools are those available in the current workspace, rather than a global pool.
Memory contains what is relevant now, rather than the entire past.
History includes recent user messages, rather than a complete replay of the conversation.
There are two ways to load this information.
Prefetching inserts selected information ahead of time: long-term user preferences, recent relevant events or commonly used experience in the workspace. It must stay short, precise and controlled.
Agentic access lets the model retrieve details when needed. It may see a summary of an old memory and open it when asked for detail, or recognize a relevant experience title and retrieve the complete method.
The runtime must clearly distinguish what is prefetched from what is loaded on demand. Without that distinction, context management becomes an undifferentiated collection again.
Switching workspaces changes Workspace Prompt, Tools, Memory and History. The System Prompt remains consistent, preserving the agent's persona and behavior.
Partition Memory
Memory design is critical to making workspaces function.
A single container called long-term memory is insufficient. People remember people, events and learned methods differently. Zleap-Agent similarly divides memory into three categories.
First, memories about people. A user may prefer direct conclusions, dislike vague language, often work on enterprise products or want Chinese responses. These memories belong to that user. When several people share an agent, one person's preferences must not affect another.
Second, memories about events. These include progress with a customer, a blocked contract or the stage where conversion fell during a campaign. They belong to both a user and a workspace. Sales follow-ups should not enter finance context, and reimbursement rules should not contaminate content work.
Third, reusable experience. Examples include reviewing the last three customer conversations before analyzing a deal, organizing weekly reports by goals, progress, risks and next steps, or first distinguishing missing receipts from budget or approval problems in reimbursements.
Experience can be shared between users, but it must be anonymized. It should preserve the method, not personal information, customer details or raw project material.
Separate workspace memories prevent contamination. Mixed memories can produce incorrect answers; in an enterprise, they can also cause security incidents.
Database-Driven
Once multiple people share an agent, the question becomes more than how to remember:
Who may see whose memories? Which workspace may access which memories? Which experience can be shared, and which information must remain isolated?
Zleap-Agent was therefore designed from day one around a database, rather than a single person's local folder.
A useful enterprise agent will be shared by sales, operations, finance, engineering and leadership. Each user has distinct preferences, permissions, history and tasks. Each workspace has distinct context, tools and memory.
A file system is not enough for this structure. It can store and retrieve raw logs, but is less suited to multi-tenant isolation, fine-grained permissions, frequent agent loops and multiple memory partitions.
The memory system participates in every agent loop. Entering a workspace requires retrieving its relevant memory. Tool calls require deciding which information to retain. Completed tasks produce event records. Shared agents must keep users' and workspaces' memories separate while allowing safe reuse of shared experience.
Database-driven design turns agent execution into a system that supports partitioning, auditing, rollback and reuse. It is more than replacing files with tables.
Conclusion
Sparse attention at the model level avoids examining every token. Workspaces at the harness level avoid exposing every piece of context.
One operates inside the model, the other around it, but both focus attention where it matters.
Zleap-Agent proposes an agent harness organized around workspaces, partitioned memory, a database foundation, model routing and clear context boundaries, rather than an ever-longer prompt.
This helps make small models practical and large models faster, more accurate and less expensive.
Today, we are also open-sourcing a preview of Zleap-Agent. It demonstrates the logic and approach, though many implementation details still need optimization. Contributions are welcome.
Tomorrow, in the final article of this series, I will share our new product ideas built on SAG and Zleap-Agent.
Keep reading
Media coverage
The Next Phase of Agents: Building the Infrastructure for Enterprise AI in China
Z Potentials examines local deployment, costs, enterprise data, SAG, Zleap-Agent, and collaboration between enterprise agents through Zleap’s approach.
Insights
Agents, Give People Better Context
How agents and SAG can organize scattered information and provide people with more complete context for decisions and collaboration.
Insights
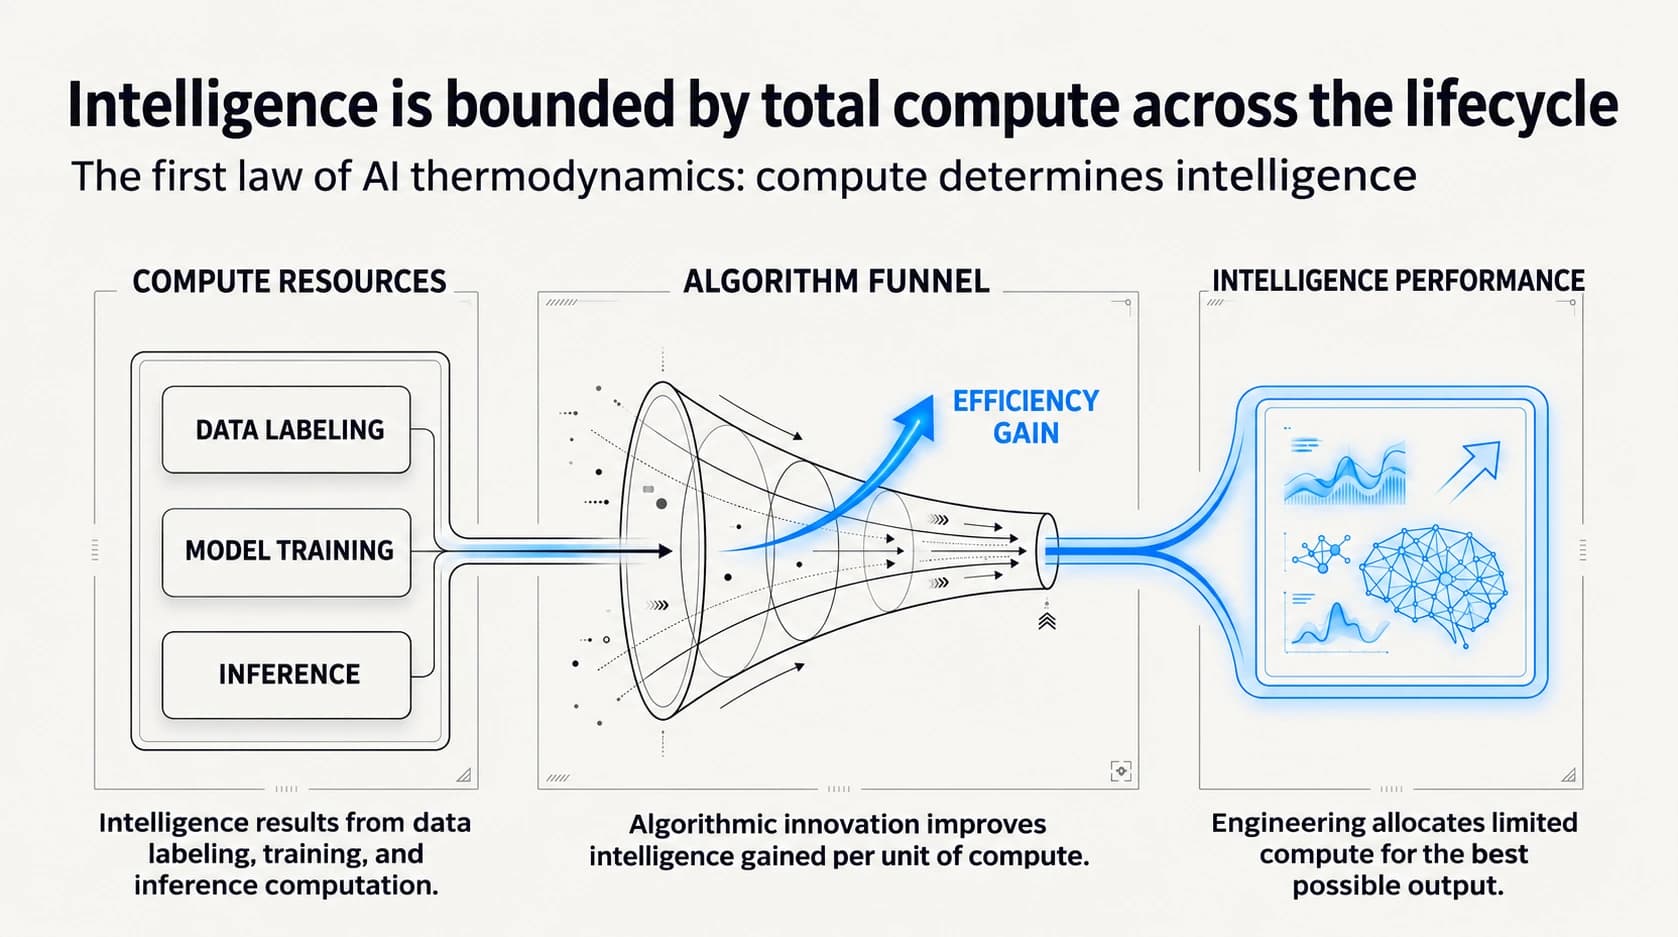
Why RAG Is Still Here in 2026: Thoughts on the Thermodynamics of AI
An engineering perspective on computation, algorithms, embeddings and LLMs, and how RAG and SAG balance speed, quality and cost.