SAG: A New RAG State of the Art and a Data Foundation for Agents
Why complex agents need a structured data foundation, and how SAG supports incremental ingestion, multi-hop retrieval and traceable evidence.
Paper: https://arxiv.org/abs/2606.15971
Open source: https://github.com/Zleap-AI/SAG
Hi, I am Jomy. This week, I will publish three articles over three days to share Zleap's recent work. Today, we begin with SAG.
Over the past two years, nearly every AI application has faced the same problem: as models improve, the quality of an agent's work increasingly depends on the context it can obtain.
When context is missing, RAG retrieves it. But one retrieval is often insufficient for complex tasks.
The increasingly popular Agentic RAG approach asks a model to retrieve repeatedly: break down the question, search, read results and decide what to look up next.
That sounds reasonable. But inaccurate searches force the model to keep reasoning, retrieving and judging. Token use and latency grow, while uncertainty compounds each round.
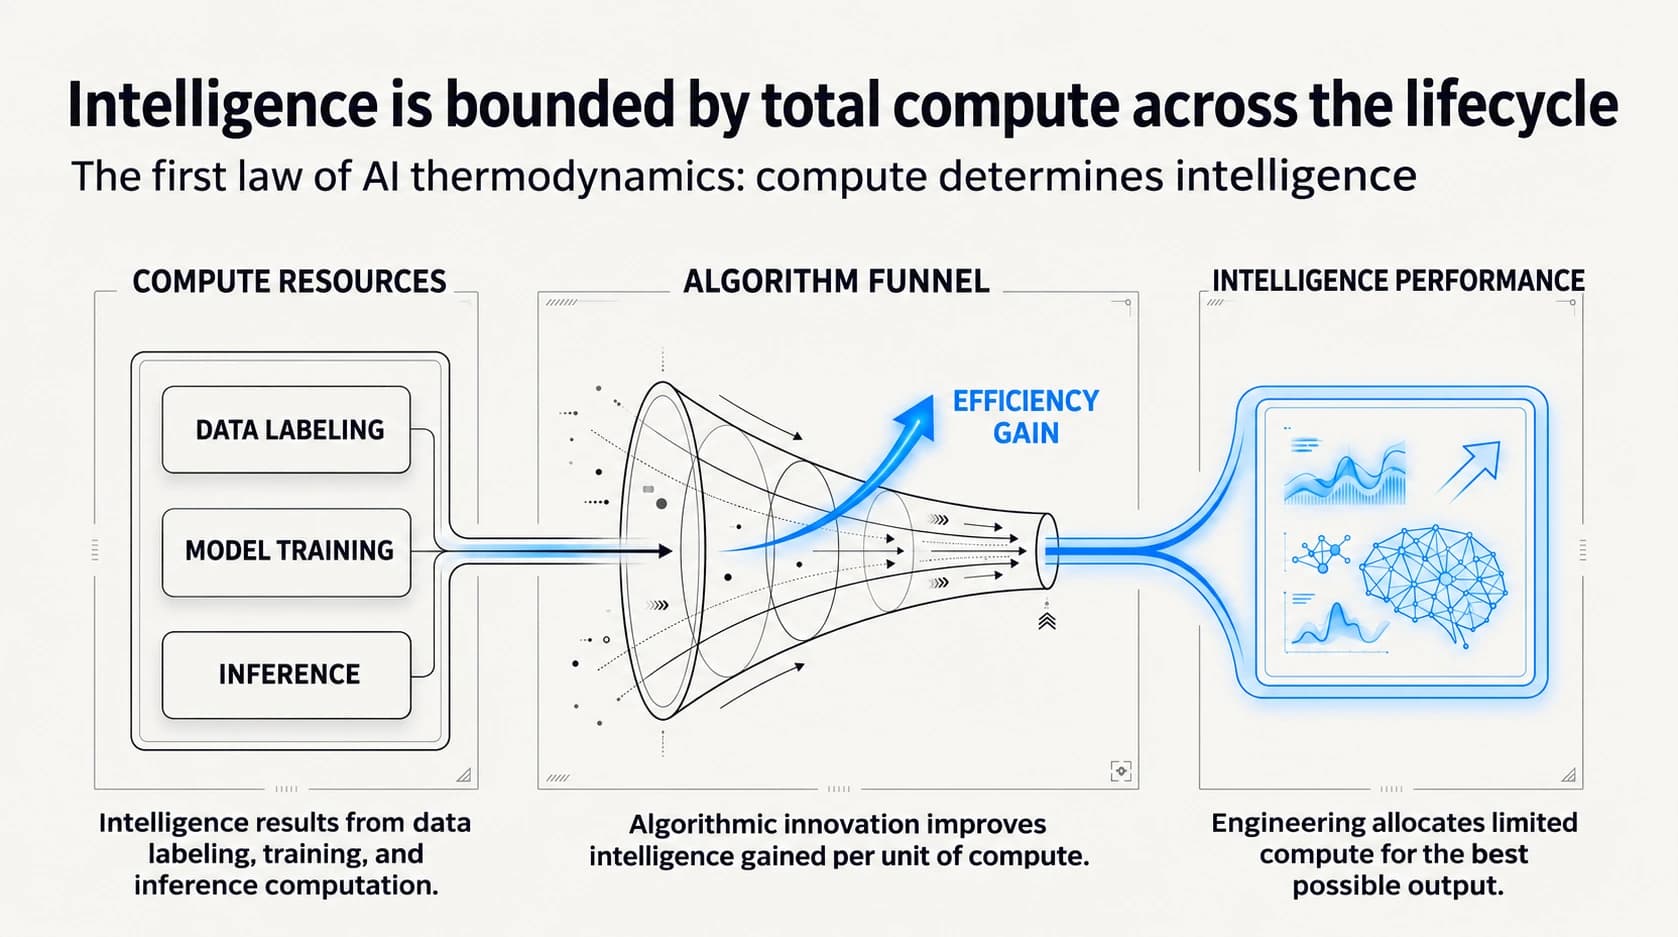
I have previously argued that intelligence depends on computation. The important question is where that computation should happen.
Should agents search, reason and assemble context from scratch for every question? Or should information be organized when it enters the system?
The issue is whether large volumes of context become a reusable data foundation, rather than simply whether agents can search more often.
That is the question this article addresses.
We spent a year researching SAG, from the initial project to the first open-source release last November, and now the paper and benchmark results. Here is why we reconsidered RAG from the ground up.
The RAG Bottleneck
Traditional vector RAG is fast. It embeds passages and retrieves those most similar to the question.
That works for small, static document collections where questions are simple and an answer is contained in one passage.
Its fundamental limitation is that similarity does not capture who or what is related, or how.
For example, a multi-hop answer might span several documents: Company A acquires Company B, B's CTO later joins Project C, and C influences a product roadmap. Individually, these details may not closely resemble the question. Together, they form the answer.
Vector RAG struggles to find that chain reliably.
GraphRAG correctly recognizes entities, relationships and structure in text. But it is also heavy. Many systems extract triples, merge entities, normalize relationships, detect communities and summarize them. Each step relies on LLMs and introduces potential errors.
Graphs also require ongoing maintenance. Real data changes every day: entities, aliases and relationships emerge, while old relationships and summaries become outdated. Maintaining a large graph can be harder than building one.
HippoRAG 2 demonstrates that retrieval needs structured memory and multi-hop connections as well as vectors. But it relies on global Personalized PageRank or similar graph ranking. That works at benchmark scale, but becomes heavy as large datasets keep growing.
An agent's data foundation must support continuous ingestion and updates, traceability and rollback. New data cannot require recomputing the global graph each time.
We therefore need a new structured document format.
From NaiveRAG to GraphRAG to SAG, heavier structure is not inherently better. What matters is support for incremental updates, multi-hop retrieval and real agent workloads.
SAG's Structure
The core structure is simple:
chunk -> event, chunk -> entities, event <-> entities
One chunk corresponds to one event. Multiple entities extracted from that same chunk are associated with the event.
Traditional graph triples instead follow:
subject -> predicate/relationship -> object
Or, in knowledge-graph terminology:
head entity -> relationship -> tail entity
For example:
SAG -> uses -> hypergraphs
SAG -> stores -> events
SAG -> supports -> multi-hop retrieval
Triples fragment a complete meaning and depend heavily on the accuracy of predicate extraction. Different models might describe the same fact with “uses,” “is based on,” “proposes” or “supports.” Real data amplifies these inconsistencies.
SAG asks the LLM to do two more stable things: summarize a chunk into a complete, independently understandable event, and extract as many relevant entities as possible from the original chunk. The entities are then connected to that event.
Events preserve meaning. Entities provide index points grounded in the source.
SAG adds a semantic index to the source material rather than trying to extract every relationship more precisely. In graph terms, it is a hyperedge: a single event organizes several entities together.
This suits RAG because answers ultimately need original evidence. Triples can lose context; events preserve it while making the information searchable and expandable.
SAG's core is a lighter, more robust data index.
A New State of the Art
Let us look at the results.
The simplified benchmark chart highlights average Recall@2, MuSiQue Recall@5 and the improvement of event hyperedges over triples.
We compared SAG with HippoRAG 2 using the same embedding and LLM configuration:
Embedding = bge-large-en-v1.5
LLM = qwen3.6-flash
The datasets were HotpotQA, 2WikiMultiHop and MuSiQue.
For average Recall@2, HippoRAG 2 scored 68.14%. SAG improved on it by 11.16 percentage points, or approximately 16.4% in relative terms.
This is more important than Recall@10. Agents need key evidence early, in fewer results. Returning more context makes the LLM read more, increasing cost, latency and interference.
MuSiQue is the harder compositional multi-hop dataset. The improvement indicates that event/entity indexing helps with complex relationships.
One qualification matters: HippoRAG 2 scores somewhat lower with bge-large-en-v1.5. Its original paper uses the larger NV-Embed-v2 model and reports approximately 74% MuSiQue Recall@5.
SAG is less sensitive to the embedding model. Its MuSiQue Recall@5 is 80.04% with bge-large-en-v1.5 and 81.71% with NV-Embed-v2, suggesting that the gains reflect the robustness of the algorithmic structure.
We also compared triples and event hyperedges. On MuSiQue, a triple-based 1-n-2 structure achieved 77.16% Recall@5. SAG's one-event-to-many-entities structure achieved 80.04%.
The lighter hyperedge structure worked better for retrieval. Triples require fine-grained relationships to be extracted accurately. SAG retains a complete event and extracts entities from the chunk for indexing.
The paper includes extensive ablation experiments supporting these choices.
The Retrieval Process
SAG has two stages: offline ingestion and online retrieval.
During ingestion, documents are split into chunks. Each chunk yields one event and multiple entities. These are written to the database, vector index and full-text index.
SAG stores a structure that supports SQL queries, vector retrieval, full-text search and multi-hop expansion, in addition to the original text.
After retrieving seed events, the system expands relationships in SQL:
- Get the entity IDs associated with seed events.
- Use the
event_entitiestable to find other events connected to those entities. - Exclude events already found, producing the next candidate set.
This is multi-hop retrieval through database relationships. It does not require global PageRank or asking an LLM to reason over an improvised graph.
Finally, events are mapped back to original chunks. Answers must rely on source evidence, rather than abstract events alone.
SAG currently has two principal modes. Fast mode prioritizes speed; high-accuracy mode prioritizes precision. Both use the event/entity index and multi-hop retrieval. The high-accuracy architecture includes LLM reranking, while fast mode omits that step.
Scaling
Scaling means being able to keep ingesting data, not simply making a graph larger.
SAG does not maintain a global knowledge graph in advance. New data is chunked, its events and entities are extracted, and the results are written to SQL. This resembles incremental database ingestion rather than global graph rebuilding.
Chunks are also natural units of concurrency. Event and entity extraction can run independently for each chunk, allowing large batches to be processed concurrently. Event extraction and event/entity/relationship embedding can all run in parallel.
What happens when concurrent extraction encounters the same entity?
We do not use expensive global entity merging or resolution. Before inserting an entity, the system normalizes its string and checks SQL. If an entity of the same type and name exists under the same source, it is reused; otherwise, it is inserted.
SAG does not require perfect entity resolution to work. Even simple normalization and deduplication produce the reported results, because entities are primarily index points. Events preserve the actual meaning.
We also tested production-scale usability. We collected large amounts of public web data, forming a database with approximately 500 million records that continues to grow. SAG remains stable at this scale.
We built a Wikipedia example so people can try multi-hop retrieval themselves, using Wikipedia content analyzed and imported into SAG.
Try it online: http://wiki.zleap.com
A Data Foundation for Agents
Why call SAG an agent data foundation?
A conventional question-answering system retrieves once and answers once. An agent may search repeatedly, following one lead to another and deciding its next action from new results.
Retrieval accuracy then affects the stability of the entire task. An incorrect first result can contaminate later reasoning. Missing a result may send the agent in the wrong direction. On difficult tasks, errors compound as searches continue.
More accurate retrieval has two benefits:
- Find the right information with fewer searches.
- Reduce the chance of errors compounding when multiple searches are necessary.
The goal is reliability across the agent's complete sequence of actions, beyond optimizing a single answer.
Memory is another application. Memories are changing data, not isolated text. The same user, project or preference can recur over time. New memories can supplement, revise or overturn older ones.
Vector memory finds similar passages, but an agent also needs to distinguish historical context from current state.
SAG fits this need: events preserve complete facts; entities connect the same people, projects, tasks and preferences; SQL stores time, sources and related IDs.
In the example above, vector retrieval might return two memories without knowing which is current. SAG connects them through the project, user and task-state entities, then uses timestamps and related IDs to find the current state.
SAG supports memory because it already indexes events, entities, time and relationships, rather than because a separate memory module was added.
That is a data structure agents can use over the long term.
Conclusion
The next stage of RAG is about redesigning how data reaches agents, rather than increasing top-k or filling larger context windows.
SAG's contribution has three parts:
- A lightweight index over source data:
chunk -> event,chunk -> entitiesandevent <-> entities. - Faster, more stable multi-hop retrieval combining SQL relationship expansion, vector retrieval and full-text search.
- Incremental ingestion, concurrent processing and continuous growth, providing a durable data foundation for agents.
SAG changes how data is organized for retrieval and agent systems. It represents a shift from text recall toward a structured data foundation.
In the next article, I will explain how we built an agent harness with sparse attention on SAG. See you tomorrow.
Keep reading
Media coverage
The Next Phase of Agents: Building the Infrastructure for Enterprise AI in China
Z Potentials examines local deployment, costs, enterprise data, SAG, Zleap-Agent, and collaboration between enterprise agents through Zleap’s approach.
Insights
Agents, Give People Better Context
How agents and SAG can organize scattered information and provide people with more complete context for decisions and collaboration.
Insights
Why RAG Is Still Here in 2026: Thoughts on the Thermodynamics of AI
An engineering perspective on computation, algorithms, embeddings and LLMs, and how RAG and SAG balance speed, quality and cost.